https://github.com/alibaba/zvec
A lightweight, lightning-fast, in-process vector database
https://github.com/alibaba/zvec
agent-skills db embedded faiss fts fulltext-search hnsw llm-memory local rag search-engine semantic-search similarity-search vector-database vector-db
Last synced: 1 day ago
JSON representation
A lightweight, lightning-fast, in-process vector database
- Host: GitHub
- URL: https://github.com/alibaba/zvec
- Owner: alibaba
- License: apache-2.0
- Created: 2025-12-05T07:45:38.000Z (11 months ago)
- Default Branch: main
- Last Pushed: 2026-10-29T09:37:09.000Z (3 days ago)
- Last Synced: 2026-10-29T21:16:13.749Z (3 days ago)
- Topics: agent-skills, db, embedded, faiss, fts, fulltext-search, hnsw, llm-memory, local, rag, search-engine, semantic-search, similarity-search, vector-database, vector-db
- Language: C++
- Homepage: https://zvec.org
- Size: 8.94 MB
- Stars: 16,161
- Watchers: 69
- Forks: 1,013
- Open Issues: 99
-
Metadata Files:
- Readme: README.md
- Contributing: CONTRIBUTING.md
- License: LICENSE
- Code of conduct: CODE_OF_CONDUCT.md
- Codeowners: .github/CODEOWNERS
- Notice: NOTICE
Awesome Lists containing this project
- awesome-cpp - alibaba/zvec - A lightweight, lightning-fast, in-process vector database (Other / Scientific Computing)
- awesome-production-machine-learning - Zvec - Zvec is an open-source, in-process vector database for low-latency similarity search. (Industry Strength Information Retrieval)
- awesome-vector-databases - Zvec - Open-source, in-process vector database by Alibaba, positioned as the SQLite of vector databases. Delivers production-grade, low-latency similarity search with minimal setup, achieving >8,000 QPS on VectorDBBench. This is an open-source (OSS) solution released under Apache 2.0 license. ([Read more](/details/zvec.md)) `Open Source` `Embedded` `Lightweight` (Vector Database Engines)
- awesome-cpp - Zvec - A lightweight, lightning-fast, in-process vector database. [Apache2] [website](https://zvec.org/) (Database)
- awesome-opensource-ai - zvec - Lightweight, lightning-fast, in-process vector database from Alibaba. Built on Proxima (Alibaba's battle-tested vector search engine) for production-grade, low-latency similarity search. Apache 2.0 licensed.  (5. Retrieval-Augmented Generation (RAG) & Knowledge)
- awesome-data-engineering - zvec - An embedded vector database for on-device RAG and edge AI, the SQLite of vector databases. (Databases)
- awesome-cpp-with-stars - Zvec - fast, in-process vector database. [Apache2] website | 2026-06-03 | (Database)
- awesome-infra-for-ai - alibaba/zvec - Zvec is an open-source, lightweight, and lightning-fast in-process vector database designed for embedding directly into applications, providing low-latency and scalable similarity search. (Model Serving & Inference / Vector Databases & Retrieval Infrastructure)
- AiTreasureBox - alibaba/zvec - 02-24_7674_221](https://img.shields.io/github/stars/alibaba/zvec.svg)|A lightweight, lightning-fast, in-process vector database| (Repos)
- awesome-llm-tools - zvec - process embedded vector database; lightweight and extremely fast (AliBaba) | Embedded RAG, local search | Apache-2.0 | (7. Vector Databases / Rust)
- fucking-awesome-python - zvec - An embedded vector database for on-device RAG and edge AI, the SQLite of vector databases. (Projects / Database)
- awesome-ai-200 - alibaba/zvec - fast, in-process vector database | (القائمة الكاملة Top 200)
- my-awesome - alibaba/zvec - skills,db,embedded,faiss,fts,fulltext-search,hnsw,llm-memory,local,rag,search-engine,semantic-search,similarity-search,vector-database,vector-db pushed_at:2026-10 star:16.1k fork:1.0k A lightweight, lightning-fast, in-process vector database (C++)
- awesome-bigdata - Zvec - open-source, in-process vector database for dense, sparse, and hybrid similarity search. (Vector Databases)
- fucking-awesome-cpp - Zvec - A lightweight, lightning-fast, in-process vector database. [Apache2] 🌎 [website](zvec.org/) (Database)
- awesome-github-projects - zvec - A lightweight, lightning-fast, in-process vector database ⭐16,098 `C++` 🔥 (🤖 AI & Machine Learning)
- awesome-x-ops - zvec - fast in-process vector database from Alibaba for embedded AI search and retrieval, Apache-2.0. (AI Infrastructure)
- awesome-python - zvec - An embedded vector database for on-device RAG and edge AI, the SQLite of vector databases. (Projects / Database)
- fucking-awesome-bigdata - Zvec - open-source, in-process vector database for dense, sparse, and hybrid similarity search. (Vector Databases)
README
English | 中文






🚀 Quickstart |
🏠 Home |
📚 Docs |
📊 Benchmarks |
🔎 DeepWiki |
🎮 Discord |
🐦 X (Twitter)
**Zvec** is an open-source, in-process vector database — lightweight, lightning-fast, and designed to embed directly into applications. Battle-tested within Alibaba Group, it delivers production-grade, low-latency and scalable similarity search with minimal setup.
> [!Important]
> 🚀 **v0.7.0 (August 24, 2026)**
>
> - **[zvec-grep](https://github.com/zvec-ai/zvec-grep) (`zg`)**: Local-first workspace search that unifies ripgrep, BM25, and vector search behind one CLI — built for humans and AI agents.
> - **[ReMe](https://github.com/agentscope-ai/ReMe) integration**: zvec is now a file store backend in ReMe, the memory management kit for agents, providing in-process HNSW ANN search.
> - **DiskANN productionization**: Adds **Linux ARM64 / macOS ARM64** support and an **io_uring** async I/O backend, with automatic fallback to the best available I/O option — no user intervention needed.
> - **Index optimization**: New **IVF-RaBitQ** index and **PQ-INT8** quantizer; RaBitQ supports runtime **AVX2 / AVX512** dispatch, so the same binary automatically picks the best path on each CPU.
> - **Deployment experience improved**: Prebuilt dynamic libraries slimmed significantly (macOS arm64 C API library 37→22 MB, **-40%**); new **musl libc / Alpine Linux** support; prebuilt SDK binaries for Linux (glibc/musl), macOS, Windows, Android, and iOS published with every release.
> - **DocIterator**: New iterator for streaming full-collection document traversal across C++, C, and Python.
> - **Full-text search**: New **N-gram tokenizer**, better suited for phrase, code, and short-text search.
>
> 👉 [Read the Release Notes](https://github.com/alibaba/zvec/releases/tag/v0.7.0) | [View Roadmap 📍](https://github.com/alibaba/zvec/issues/309)
## 💫 Features
- **Blazing Fast**: Searches billions of vectors in milliseconds.
- **Simple, Just Works**: [Install](#-installation) and start searching in seconds. Pure local, no servers, no config, no fuss.
- **Dense + Sparse Vectors**: Support dense and sparse embeddings, multi-vector queries, and a rich selection of [vector index types](https://zvec.org/en/docs/db/concepts/vector-index/#vector-index-types) that scale from memory to disk.
- **Full-Text Search (FTS)**: Native keyword-based full-text search — query string fields with natural-language or structured expressions.
- **Hybrid Search**: Fuse vector similarity, full-text search, and structured filters in a single query for precise results.
- **Durable Storage**: Write-ahead logging (WAL) guarantees persistence — data is never lost, even on process crash or power failure.
- **Concurrent Access**: Multiple processes can read the same collection simultaneously; writes are single-process exclusive.
- **Runs Anywhere**: As an in-process library, Zvec runs wherever your code runs — notebooks, servers, CLI tools, or even edge devices.
## 📦 Installation
Zvec offers official SDKs across multiple languages:
- **[Python](https://pypi.org/project/zvec/)**: `pip install zvec` (requires 64-bit Python 3.10–3.14)
- **[Node.js](https://www.npmjs.com/package/@zvec/zvec)**: `npm install @zvec/zvec`
- **[Go](https://github.com/zvec-ai/zvec-go)**: High-performance Go bindings.
- **[Rust](https://crates.io/crates/zvec-rust)**: `cargo add zvec-rust`
- **[Dart/Flutter](https://pub.dev/packages/zvec)**: `flutter pub add zvec`
Searching code or documents? Try **[zvec-grep](https://github.com/zvec-ai/zvec-grep)** (`zg`) — a local-first search CLI that unifies ripgrep, BM25, and vector search, built for humans and AI agents.
Prefer a visual tool? Try **[Zvec Studio](https://github.com/zvec-ai/zvec-studio)** to browse data and debug queries — no code required.
### ✅ Supported Platforms
- Linux (x86_64, ARM64; glibc & musl)
- macOS (ARM64, x86_64)
- Windows (x86_64)
### 🛠️ Building from Source
If you prefer to build Zvec from source, please check the [Building from Source](https://zvec.org/en/docs/db/build/) guide.
## ⚡ One-Minute Example
```python
import zvec
# Define collection schema
schema = zvec.CollectionSchema(
name="example",
vectors=zvec.VectorSchema("embedding", zvec.DataType.VECTOR_FP32, 4),
)
# Create collection
collection = zvec.create_and_open(path="./zvec_example", schema=schema)
# Insert documents
collection.insert([
zvec.Doc(id="doc_1", vectors={"embedding": [0.1, 0.2, 0.3, 0.4]}),
zvec.Doc(id="doc_2", vectors={"embedding": [0.2, 0.3, 0.4, 0.1]}),
])
# Search by vector similarity
results = collection.query(
zvec.Query(field_name="embedding", vector=[0.4, 0.3, 0.3, 0.1]),
topk=10
)
# Results: list of {'id': str, 'score': float, ...}, sorted by relevance
print(results)
```
## 📈 Performance at Scale
Zvec delivers exceptional speed and efficiency, making it ideal for demanding production workloads.
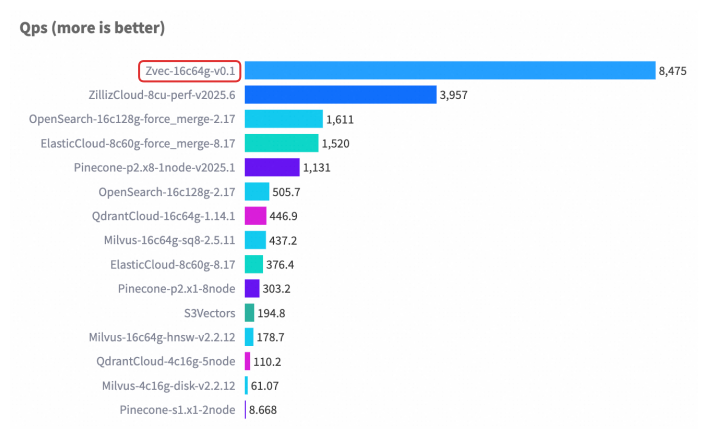
For detailed benchmark methodology, configurations, and complete results, please see our [Benchmarks documentation](https://zvec.org/en/docs/db/benchmarks/).
## 🤝 Join Our Community
| 💬 DingTalk | 📱 WeChat | 🎮 Discord | X (Twitter) |
| :---: | :---: | :---: | :---: |
|  |
 | [](https://discord.gg/rKddFBBu9z) | []() |
| Scan to join | Scan to join | Click to join | Click to follow |
## ❤️ Contributing
We welcome and appreciate contributions from the community! Whether you're fixing a bug, adding a feature, or improving documentation, your help makes Zvec better for everyone.
Check out our [Contributing Guide](./CONTRIBUTING.md) to get started!