https://github.com/sfu-db/connector-x
Fastest library to load data from DB to DataFrames in Rust and Python
https://github.com/sfu-db/connector-x
cpp database dataframe python rust sql
Last synced: 16 days ago
JSON representation
Fastest library to load data from DB to DataFrames in Rust and Python
- Host: GitHub
- URL: https://github.com/sfu-db/connector-x
- Owner: sfu-db
- License: mit
- Created: 2021-01-13T22:21:03.000Z (almost 6 years ago)
- Default Branch: main
- Last Pushed: 2026-10-13T16:05:05.000Z (22 days ago)
- Last Synced: 2026-10-14T07:41:17.332Z (21 days ago)
- Topics: cpp, database, dataframe, python, rust, sql
- Language: Rust
- Homepage: https://sfu-db.github.io/connector-x
- Size: 251 MB
- Stars: 2,661
- Watchers: 34
- Forks: 227
- Open Issues: 174
-
Metadata Files:
- Readme: README.md
- Contributing: CONTRIBUTING.md
- License: LICENSE
Awesome Lists containing this project
- awesome-python-rs - connector-x - Fastest library to load data from databases into DataFrames. (Data Processing & DataFrames)
README
# ConnectorX [![status][ci_badge]][ci_page] [![discussions][discussion_badge]][discussion_page] [![Downloads][download_badge]][download_page]
[ci_badge]: https://github.com/sfu-db/connector-x/actions/workflows/ci.yml/badge.svg?branch=main&event=push
[ci_page]: https://github.com/sfu-db/connector-x/actions/workflows/ci.yml
[discussion_badge]: https://img.shields.io/badge/Forum-Github%20Discussions-blue
[discussion_page]: https://github.com/sfu-db/connector-x/discussions
[download_badge]: https://pepy.tech/badge/connectorx
[download_page]: https://pepy.tech/project/connectorx
Load data from  to
 , the fastest way.
ConnectorX enables you to load data from databases into Python in the fastest and most memory efficient way.
What you need is one line of code:
```python
import connectorx as cx
cx.read_sql("postgresql://username:password@server:port/database", "SELECT * FROM lineitem")
```
Optionally, you can accelerate the data loading using parallelism by specifying a partition column.
```python
import connectorx as cx
cx.read_sql("postgresql://username:password@server:port/database", "SELECT * FROM lineitem", partition_on="l_orderkey", partition_num=10)
```
The function will partition the query by **evenly** splitting the specified column to the amount of partitions.
ConnectorX will assign one thread for each partition to load and write data in parallel.
Currently, we support partitioning on **numerical** columns (**cannot contain NULL**) for **SPJA** queries.
**Experimental: We are now providing federated query support, you can write a single query to join tables from two or more databases!**
```python
import connectorx as cx
db1 = "postgresql://username1:password1@server1:port1/database1"
db2 = "postgresql://username2:password2@server2:port2/database2"
cx.read_sql({"db1": db1, "db2": db2}, "SELECT * FROM db1.nation n, db2.region r where n.n_regionkey = r.r_regionkey")
```
By default, we pushdown all joins from the same data source. More details for setup and configuration can be found [here](https://github.com/sfu-db/connector-x/blob/main/Federation.md).
Check out more detailed usage and examples [here](https://sfu-db.github.io/connector-x/api.html). A general introduction of the project can be found in this [blog post](https://towardsdatascience.com/connectorx-the-fastest-way-to-load-data-from-databases-a65d4d4062d5).
# Installation
```bash
pip install connectorx
```
Check out [here](https://sfu-db.github.io/connector-x/install.html#build-from-source-code) to see how to build python wheel from source.
# Performance
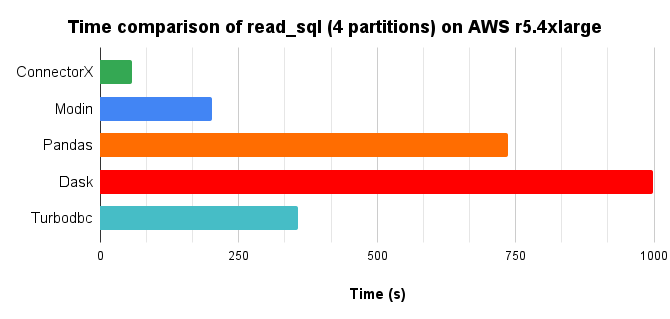
We compared different solutions in Python that provides the `read_sql` function, by loading a 10x TPC-H lineitem table (8.6GB) from Postgres into a DataFrame, with 4 cores parallelism.
## Time chart, lower is better.
## Memory consumption chart, lower is better.
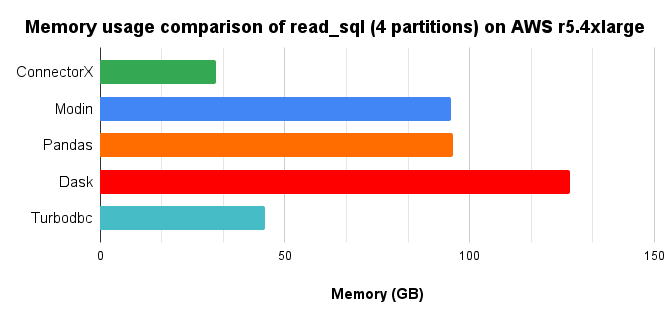
In conclusion, ConnectorX uses up to **3x** less memory and **21x** less time (**3x** less memory and **13x** less time compared with Pandas.). More on [here](https://github.com/sfu-db/connector-x/blob/main/Benchmark.md#benchmark-result-on-aws-r54xlarge).
## How does ConnectorX achieve a lightning speed while keeping the memory footprint low?
We observe that existing solutions more or less do data copy multiple times when downloading the data.
Additionally, implementing a data intensive application in Python brings additional cost.
ConnectorX is written in Rust and follows "zero-copy" principle.
This allows it to make full use of the CPU by becoming cache and branch predictor friendly. Moreover, the architecture of ConnectorX ensures the data will be copied exactly once, directly from the source to the destination.
## How does ConnectorX download the data?
Upon receiving the query, e.g. `SELECT * FROM lineitem`, ConnectorX will first get the schema of the result set. Depending on the data source, this process may involve issuing a `LIMIT 0` query `SELECT * FROM lineitem LIMIT 0`.
Then, if `partition_on` is specified, ConnectorX will issue `SELECT MIN($partition_on), MAX($partition_on) FROM (SELECT * FROM lineitem)` to know the range of the partition column.
After that, the original query is split into partitions based on the min/max information, e.g. `SELECT * FROM (SELECT * FROM lineitem) WHERE $partition_on > 0 AND $partition_on < 10000`.
ConnectorX will then run a count query to get the partition size (e.g. `SELECT COUNT(*) FROM (SELECT * FROM lineitem) WHERE $partition_on > 0 AND $partition_on < 10000`). If the partition
is not specified, the count query will be `SELECT COUNT(*) FROM (SELECT * FROM lineitem)`.
Finally, ConnectorX will use the schema info as well as the count info to allocate memory and download data by executing the queries normally.
Once the downloading begins, there will be one thread for each partition so that the data are downloaded in parallel at the partition level. The thread will issue the query of the corresponding
partition to the database and then write the returned data to the destination row-wise or column-wise (depends on the database) in a streaming fashion.
# Supported Sources & Destinations
Example connection string, supported protocols and data types for each data source can be found [here](https://sfu-db.github.io/connector-x/databases.html).
For more planned data sources, please check out our [discussion](https://github.com/sfu-db/connector-x/discussions/61).
## Sources
- [x] Postgres
- [x] Mysql
- [x] Mariadb (through mysql protocol)
- [x] Sqlite
- [x] Redshift (through postgres protocol)
- [x] Clickhouse
- [x] SQL Server
- [x] Azure SQL Database (through mssql protocol)
- [x] Oracle
- [x] Big Query
- [x] Trino
- [ ] ODBC (WIP)
- [ ] ...
## Destinations
- [x] Pandas
- [x] PyArrow
- [x] Modin (through Pandas)
- [x] Dask (through Pandas)
- [x] Polars (through PyArrow)
# Documentation
Doc: https://sfu-db.github.io/connector-x/intro.html
Rust docs: [stable](https://docs.rs/connectorx) [nightly](https://sfu-db.github.io/connector-x/connectorx/)
# Next Plan
Checkout our [discussion][discussion_page] to participate in deciding our next plan!
# Historical Benchmark Results
https://sfu-db.github.io/connector-x/dev/bench/
# Developer's Guide
Please see [Developer's Guide](https://github.com/sfu-db/connector-x/blob/main/CONTRIBUTING.md) for information about developing ConnectorX.
# Supports
You are always welcomed to:
1. Ask questions & propose new ideas in our github [discussion][discussion_page].
2. Ask questions in stackoverflow. Make sure to have #connectorx attached.
# Organizations and Projects using ConnectorX
[ ](https://github.com/pola-rs/polars)
[ ](https://dataprep.ai/)
[ ](https://modin.readthedocs.io)
To add your project/organization here, reply our post [here](https://github.com/sfu-db/connector-x/discussions/146)
# Citing ConnectorX
If you use ConnectorX, please consider citing the following paper:
Xiaoying Wang, Weiyuan Wu, Jinze Wu, Yizhou Chen, Nick Zrymiak, Changbo Qu, Lampros Flokas, George Chow, Jiannan Wang, Tianzheng Wang, Eugene Wu, Qingqing Zhou. [ConnectorX: Accelerating Data Loading From Databases to Dataframes.](https://www.vldb.org/pvldb/vol15/p2994-wang.pdf) _VLDB 2022_.
BibTeX entry:
```bibtex
@article{connectorx2022,
author = {Xiaoying Wang and Weiyuan Wu and Jinze Wu and Yizhou Chen and Nick Zrymiak and Changbo Qu and Lampros Flokas and George Chow and Jiannan Wang and Tianzheng Wang and Eugene Wu and Qingqing Zhou},
title = {ConnectorX: Accelerating Data Loading From Databases to Dataframes},
journal = {Proc. {VLDB} Endow.},
volume = {15},
number = {11},
pages = {2994--3003},
year = {2022},
url = {https://www.vldb.org/pvldb/vol15/p2994-wang.pdf},
}
```
# Contributors

Michele Bianchi

Saurabh Singh

Thomas Schmelzer

Valentino Constantinou

Santosh Pingale

Vincent HAYS

Will Eaton

Joe

Giacomo Saccaggi

Jason

Pang Jun Rong (Jayden)

oystersuki

EricFecteau

Yuan

dbascoules

Xiaoying Wang

Weiyuan Wu

Null

Yizhou

ZhengYu, Xu

Dominik Liebler

Anatoly Bugakov

Jordan M. Young

Rafael Passos

Kumar Aditya

Marko Grujic

Null

Alec Wang

Lulzim Bilali

Ritchie Vink

David Hewitt

Nicolas Pennequin

QP Hou

Jesse Grabowski

Null

CbQu

Null

Chitral Verma
Louis Maddox

Jorge Leitao

Glenn Pierce

tvandelooij

Shel Kong

Matthew Anderson

Jakku Sakura

Hieu Minh Nguyen

FerriLuli

Devin Christensen

DeflateAwning

Alexander Beedie

Meir

Ralph Ursprung

Ricardo Valero de la Rosa

Null

hieuit095

Kotval

Messense

Null

Ivan

Null

Alexander Butler

Knota Lab

Null

Mats Eikeland Mollestad

Mariano Guerra

Lukasz Gralak

Kevin Heavey

Kay Hoogland

Jaroslav Cerman

DeepSource Bot

David Beal

Andrew Jackson

Brandon

Amar Paul

Aljaž Mur Eržen

Aimilios Tsouvelekakis